Author: Reena Sethy is a Director, Product Management at Anaplan.
We are excited to announce the official release of our new bidirectional Databricks connector within Anaplan Data Orchestrator (ADO). This release provides data integration between Databricks and Anaplan, giving users seamless read and write capabilities directly within their ADO pipelines.
Key capabilities
- Read/Write integration: Easily import data from Databricks tables into ADO Datasets or Anaplan models, or write transformed data or planning output back to Databricks.
- Flexible dataset updates: Choose how to handle incoming data with support for Upsert, Append, or Replace update modes.
- Enable notifications: Enable notifications in the pipeline to be updated about the run.
- Automated scheduling: Include import and writeback pipelines in ADO Workflow for automated data syncs.
Prerequisites
Before configuring the connector, ensure you have set up a Service Principal account in Databricks with appropriate access permissions. This account credentials will be used to establish the connection from ADO.
How to import data from Databricks
To ingest data from a Databricks table/views into an ADO Dataset or Anaplan Model:
Create Pipeline: Start a new pipeline in ADO and select Databricks as your source, choosing your configured Databricks connection.
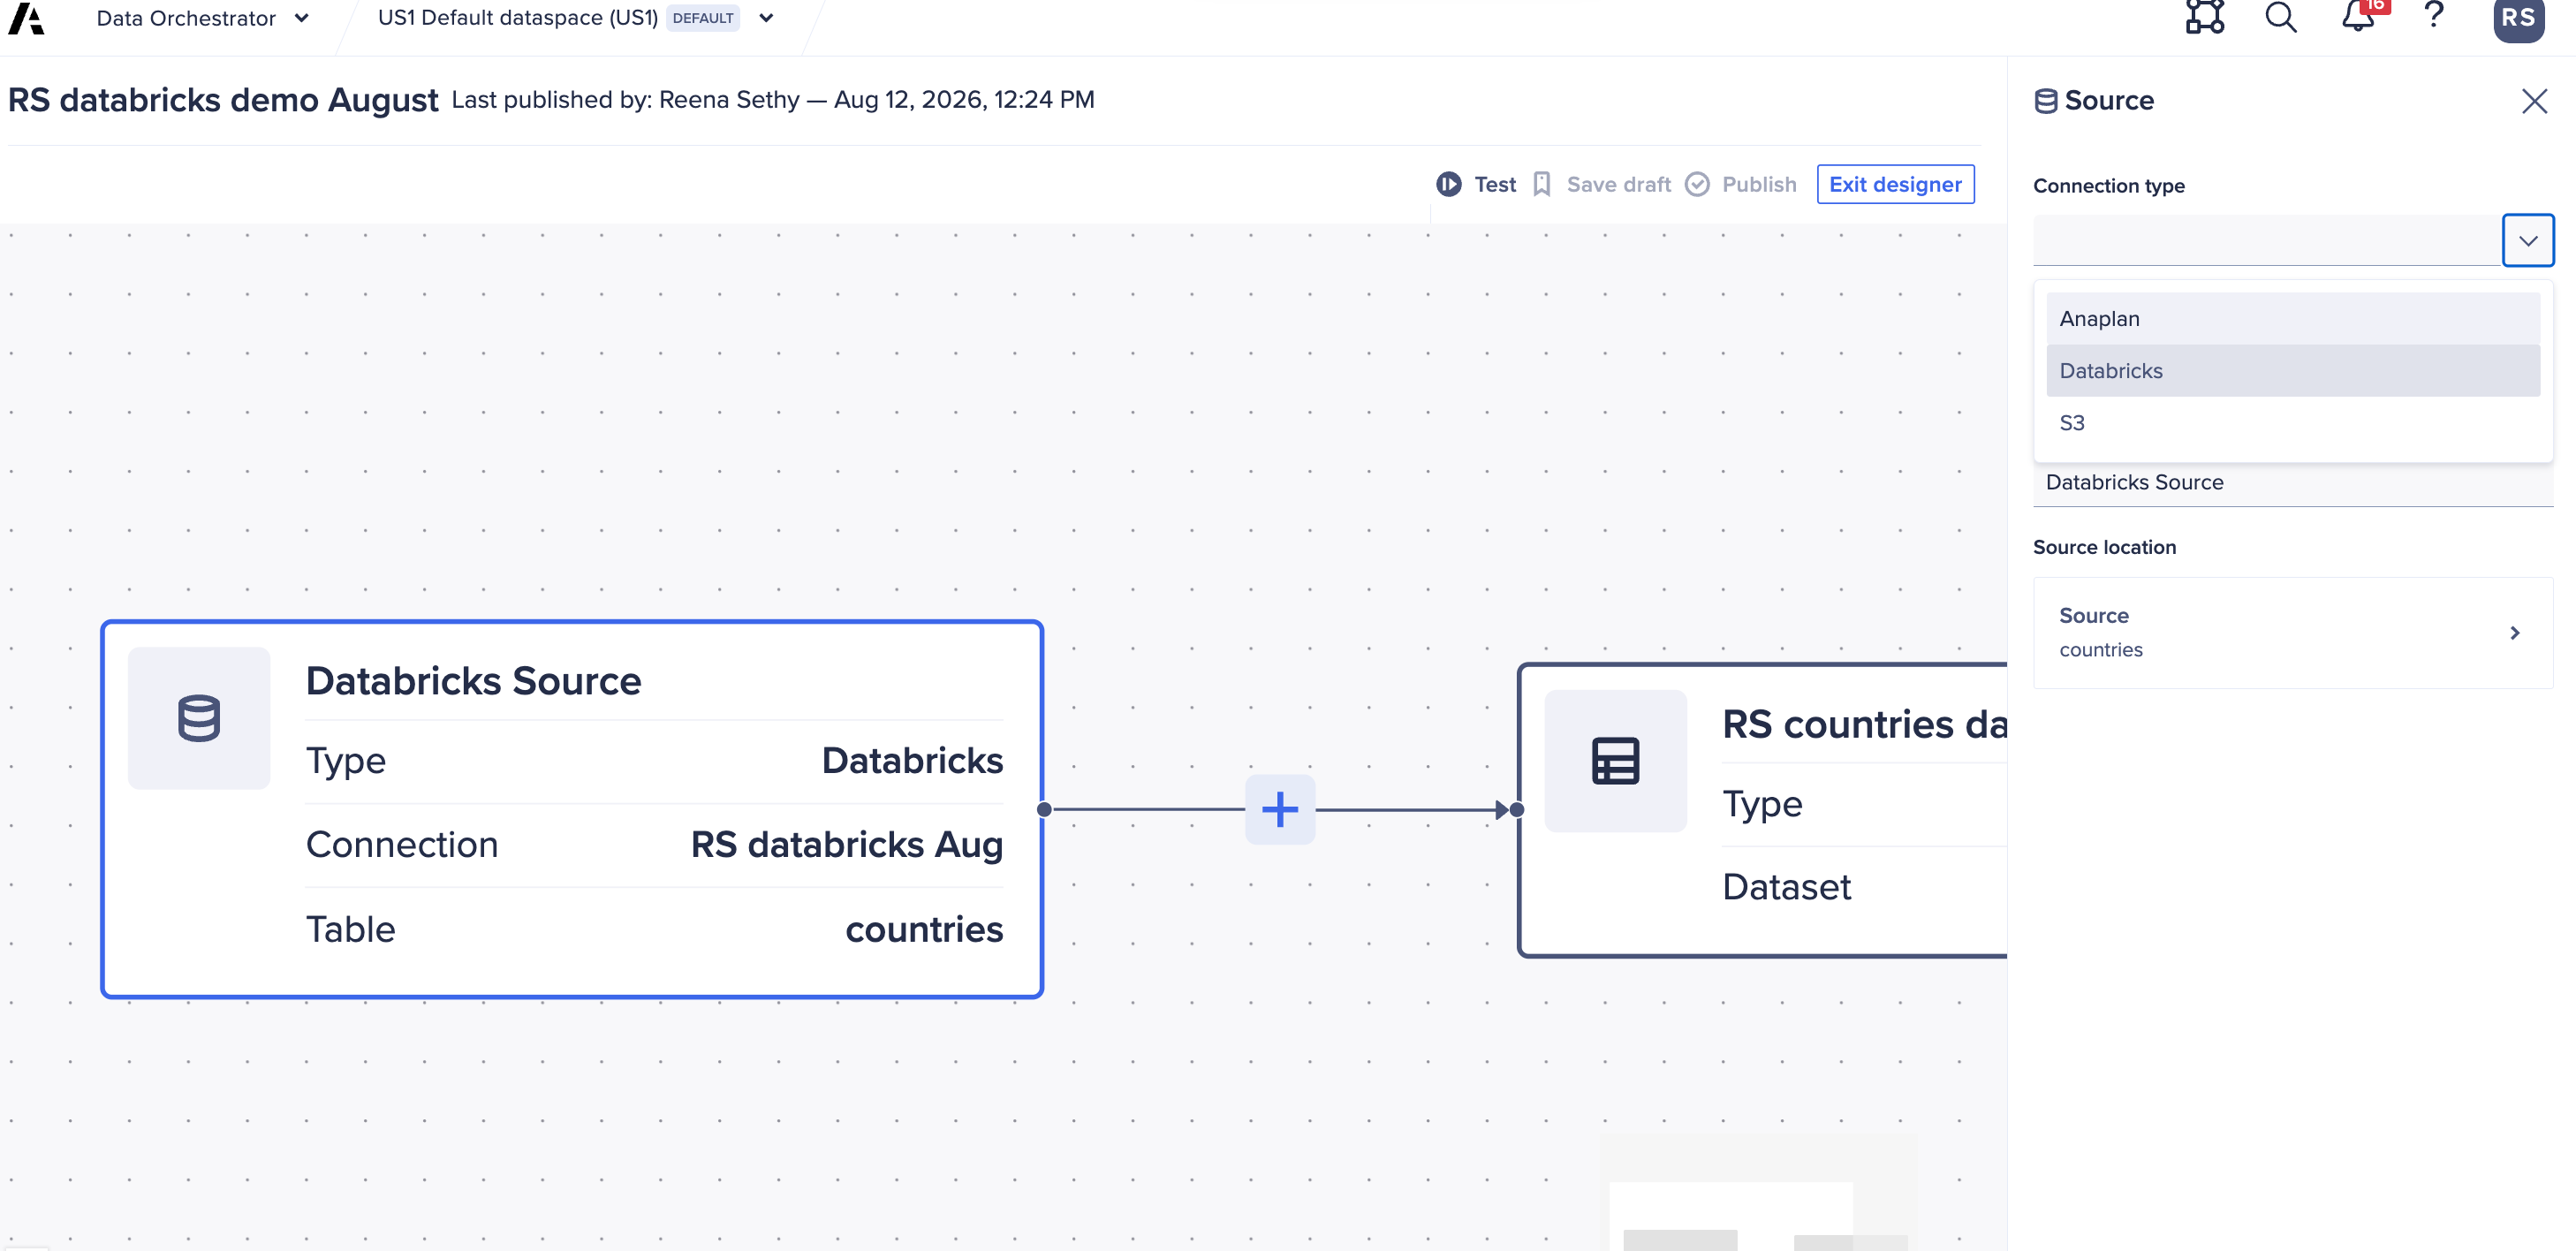
- Select Source Table: Choose the specific Databricks table you wish to import.
- Configure Sink: Set the pipeline sink as either Anaplan dataset or Anaplan Model.
- If targeting a Dataset, choose New Dataset or Existing Dataset.
- Select your preferred update mode: Upsert, Append, or Replace.
- Publish & Run: Publish the pipeline and execute a run to import your Databricks table data into ADO.
- Schedule (optional): Add the pipeline to an ADO Workflow to automate execution at defined intervals or specific times.
How to writeback data to Databricks
To execute writeback from ADO to Databricks:
- Create Pipeline: Start a new pipeline and set your source as an ADO Dataset or Transformation View.
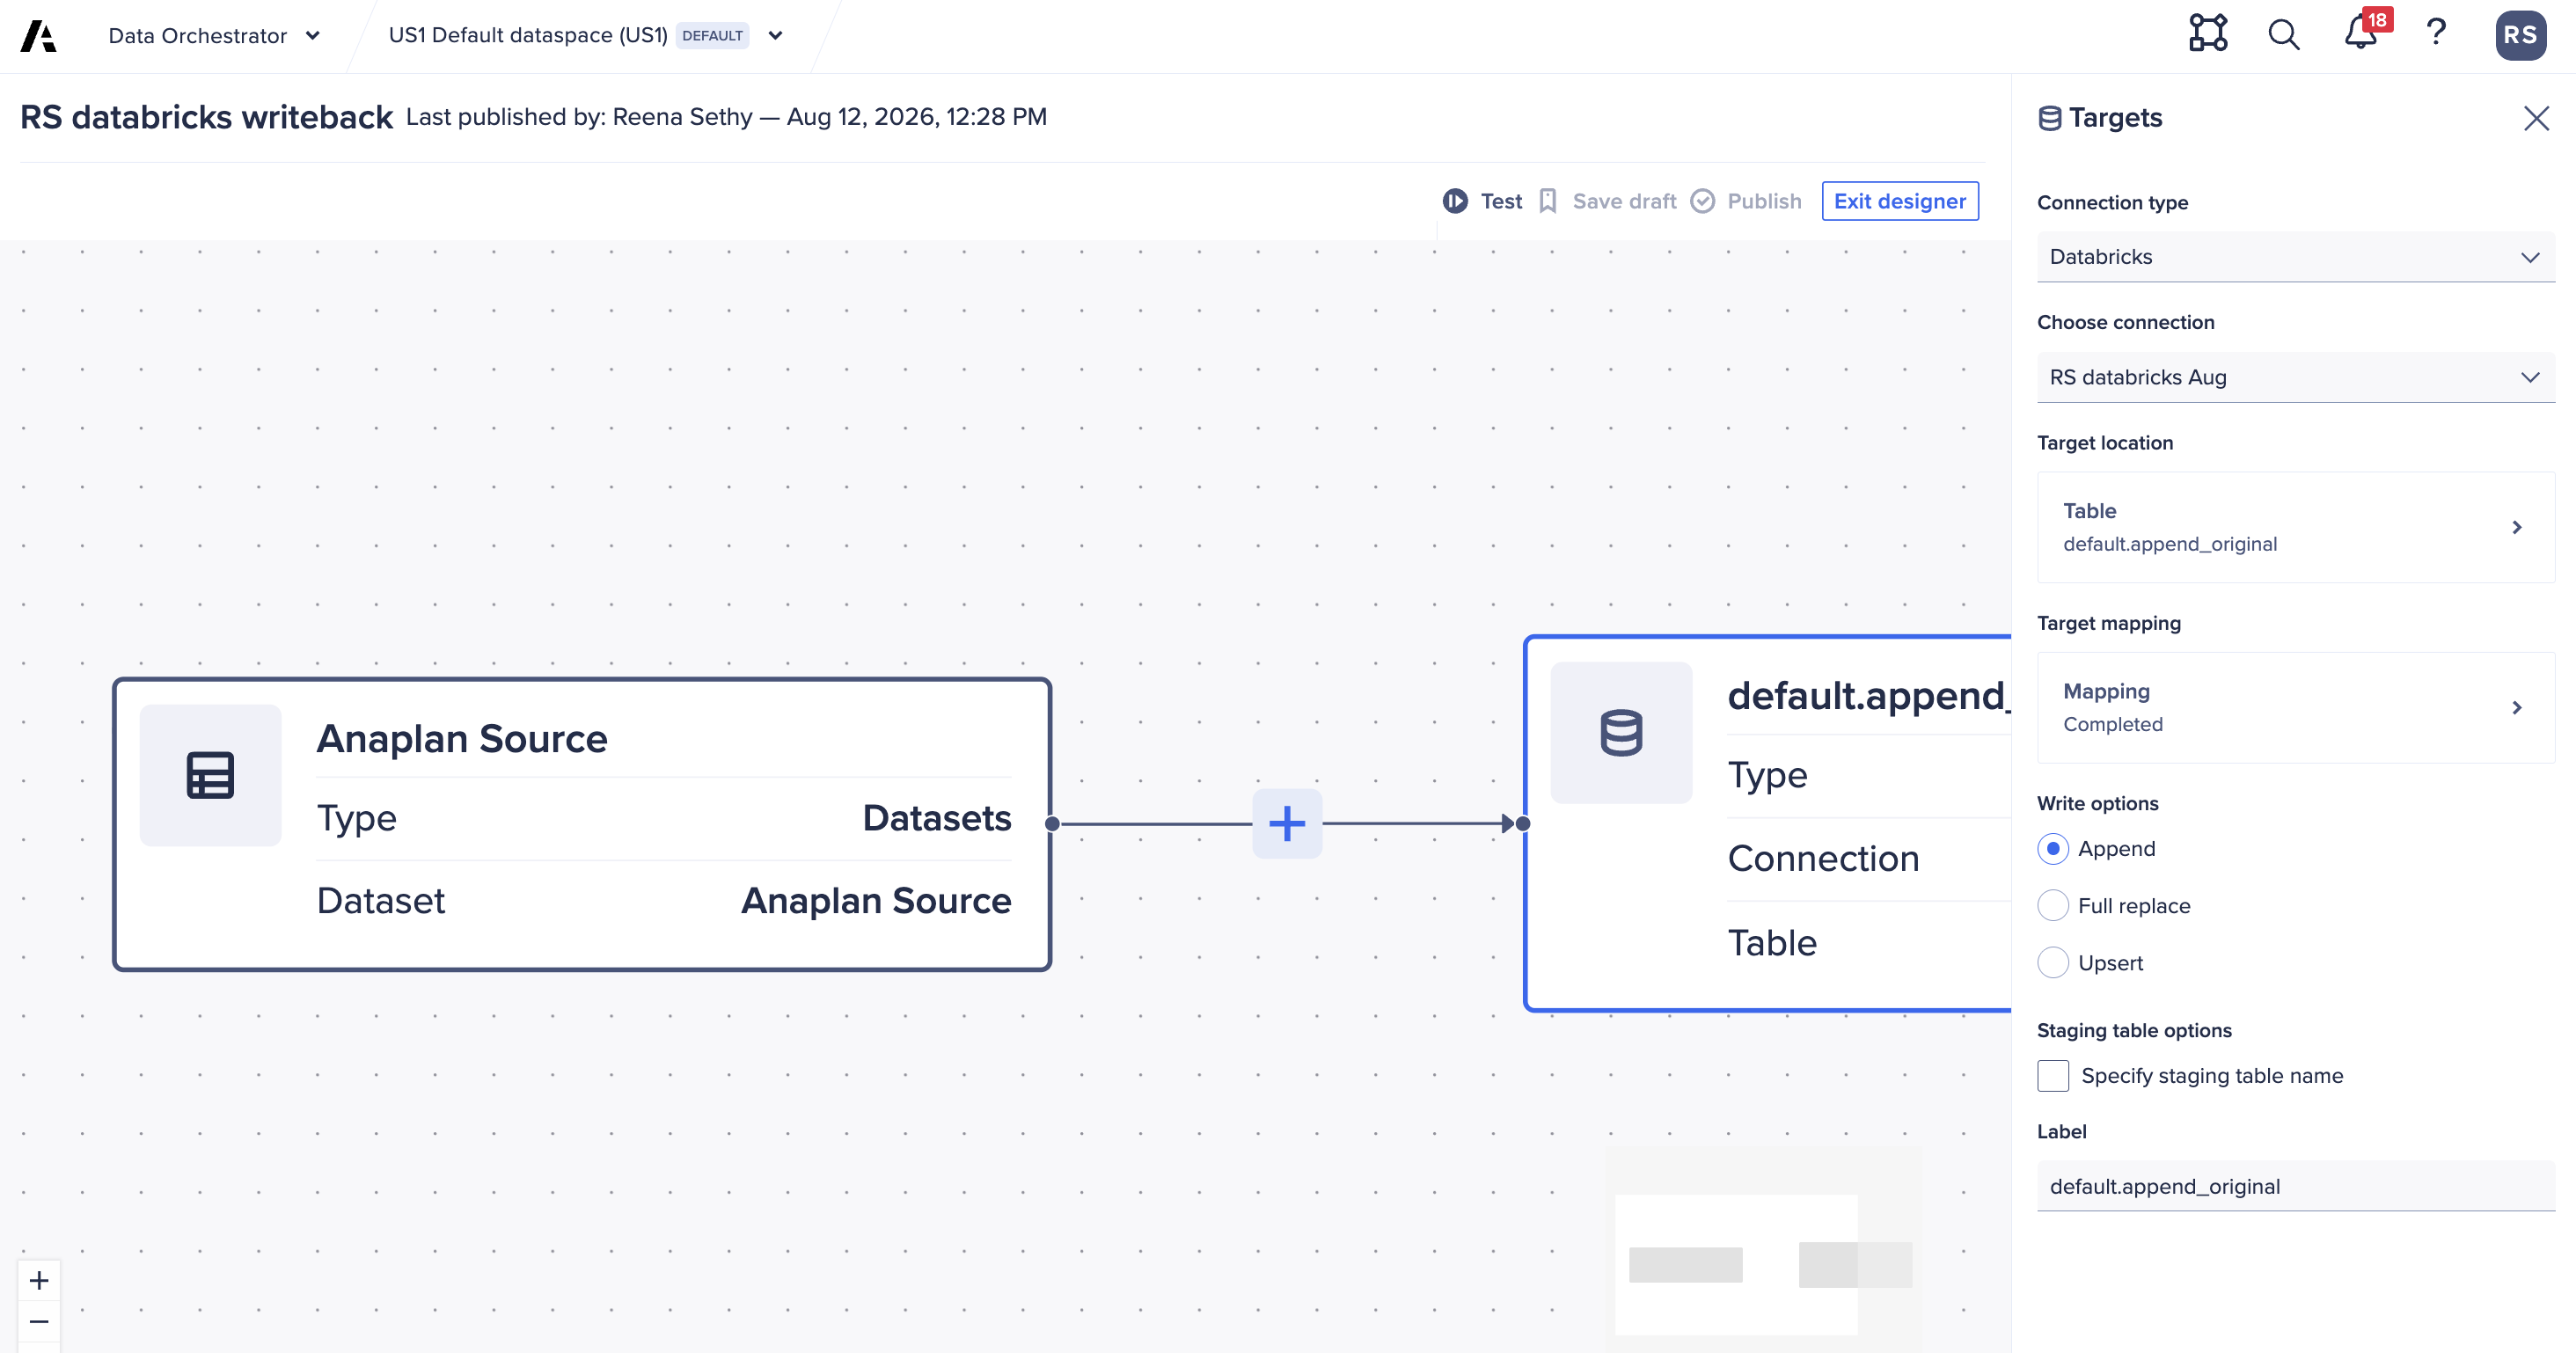
- Configure Sink: Set the sink to your Databricks table using the appropriate Databricks connection.
- Select Destination Table: Pick the target table in Databricks where the data should be written.
- Map & Complete: Map your fields, complete the configuration settings, writeback mode (Append, Upsert, Replace) and publish the pipeline to execute.
- Optional schedule: The writeback pipeline can be runs at defined intervals or specific times through ADO Workflow.
Stay connected for more connectivity options to various other systems within ADO pipelines.
Questions? Leave a comment!
……………
More from Reena:
